Improved Network Robustness with Adversary Critic
Abstract
Ideally, what confuses a neural network should be confusing to humans. However, recent experiments have shown that small, imperceptible perturbations can change the network prediction. To address this gap in perception, we propose a novel approach for learning a robust classifier. Our main idea is: adversarial examples for the robust classifier should be indistinguishable from the regular data of the adversarial target. We formulate learning a robust classifier in the framework of Generative Adversarial Networks (GAN), where the adversarial attack on the classifier acts as a generator, and the critic network learns to distinguish between regular and adversarial images. The classifier cost is augmented with the objective that its adversarial examples should confuse the adversary critic. To improve the stability of the adversarial mapping, we introduce an adversarial cycle-consistency constraint which ensures that the adversarial mapping of the adversarial examples is close to the original. In the experiments, we show the effectiveness of our defense. Our method surpasses, in terms of robustness, networks trained with adversarial training. Additionally, we verify in experiments with human annotators that adversarial examples are indeed visually confusing.
TL;DR
Core Idea
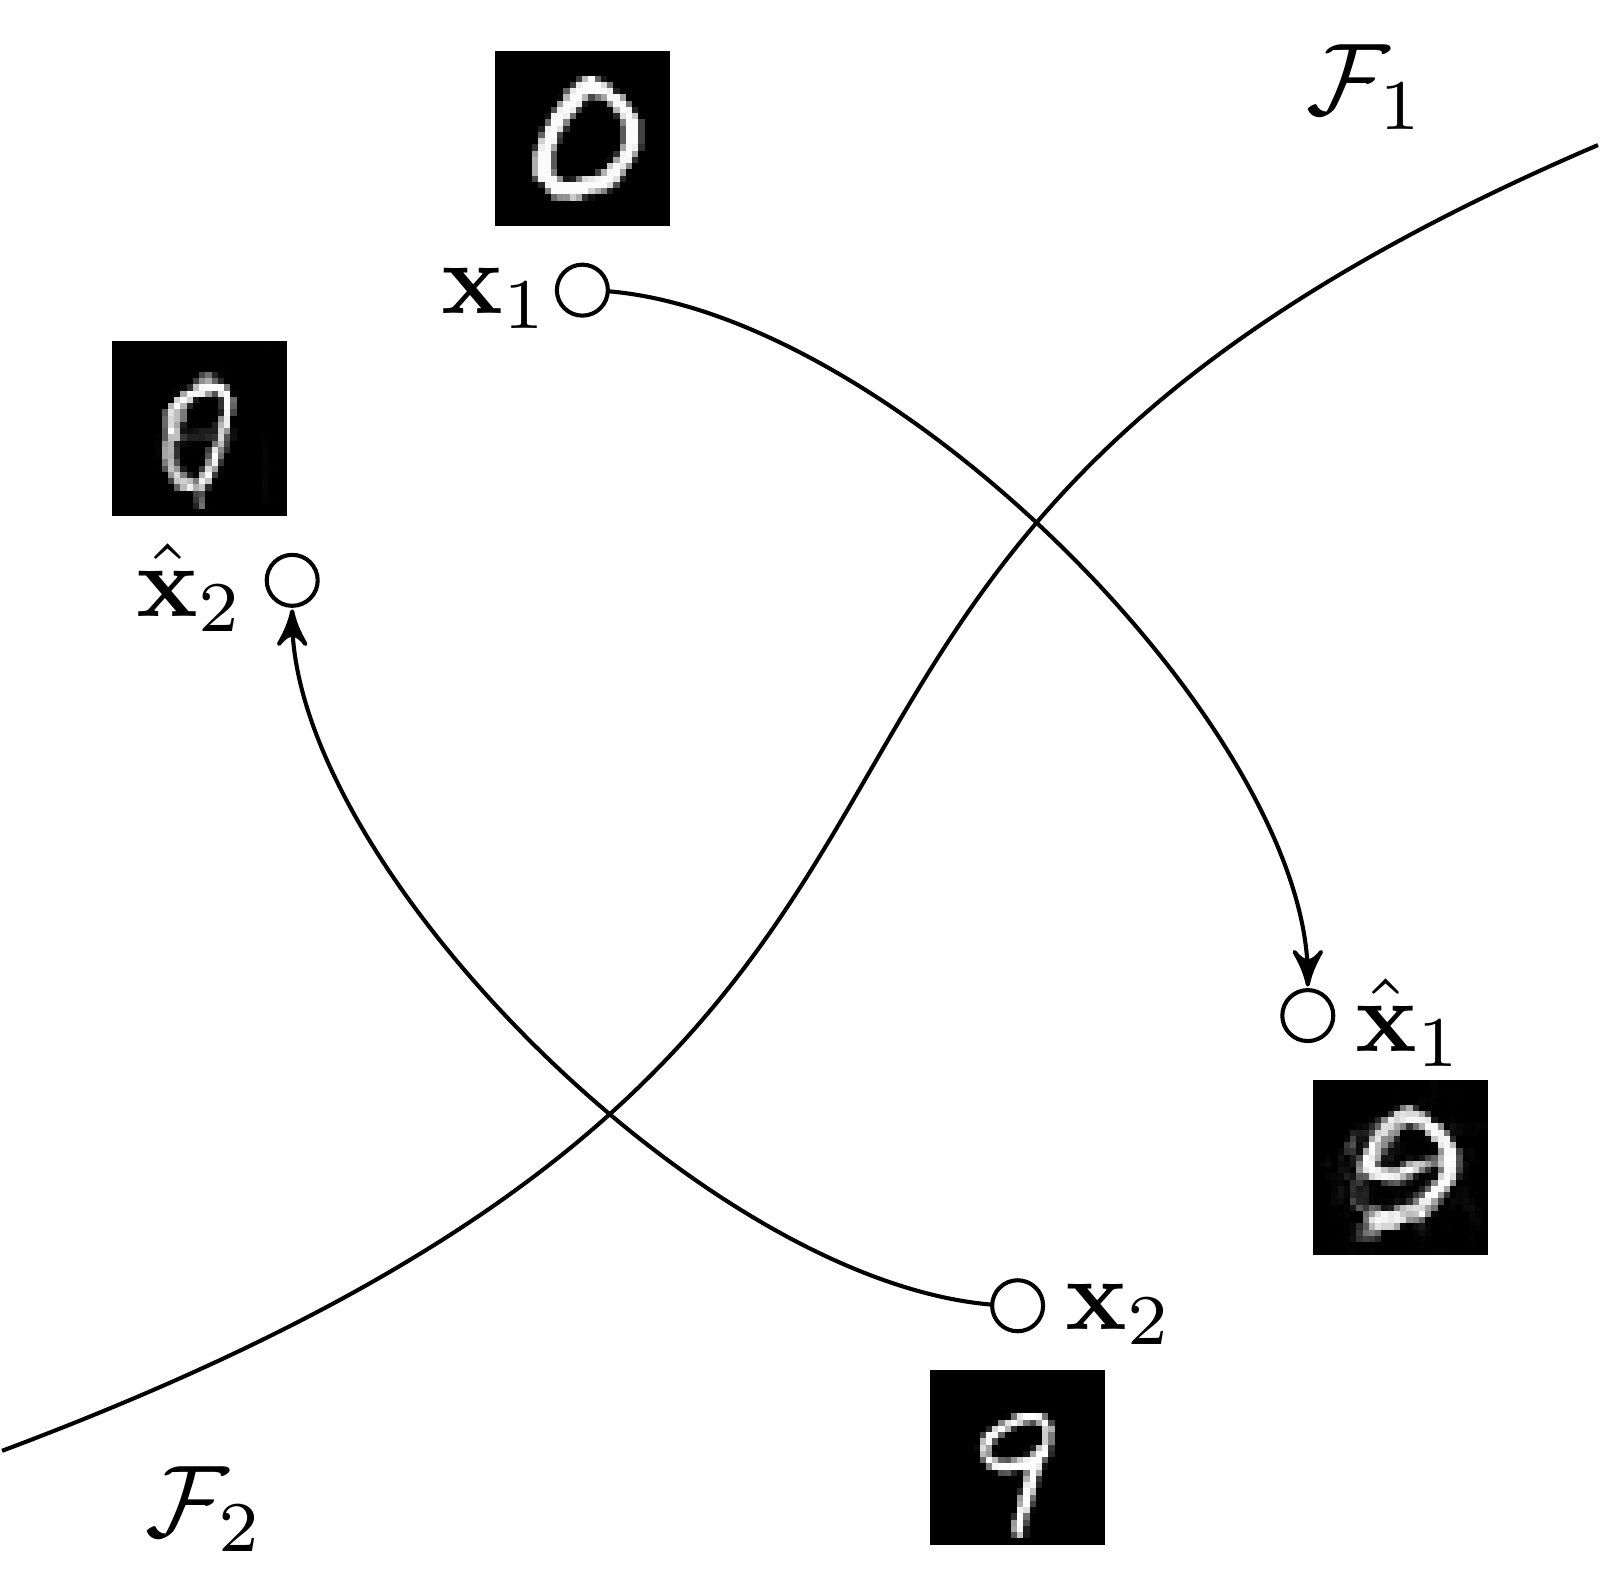
We define a classifier as perceptually robust if its adversarial examples are indistinguishable from the natural data of the adversarial target class. So the changes introduced by the adversarial noise should be associated with removing identifying characteristics of the original label and adding identifying characteristics of the adversarial label. Formally, we define the problem of learning robust classifier as follows:
$$\min_{f} \, \sum_{i=1}^{N} \mathcal{L}\big(f(\boldsymbol{x}_i), y_i\big) \, + \, \lambda \, \mathcal{D}\big[ p_{\text{data}}(\boldsymbol{x}, y), \, p_{\text{adv}}(\boldsymbol{x}, y) \big]$$
where $\mathcal{L}(\cdot,\cdot)$ is the classification loss, $p_{\text{data}}(\boldsymbol{x}, y)$ is the data distribution, $p_{\text{adv}}(\boldsymbol{x}, y)$ is the distribution of adversarial examples generated by an adversarial attack $\mathcal{A}_f$ on the classifier $f$, $\mathcal{D}(\cdot,\cdot)$ is a measure of distance between two distributions, and \(\lambda\) controls the trade-off between accuracy and robustness. The first term encourages accuracy on clean inputs, while the second enforces that adversarial examples are statistically indistinguishable from regular data of the adversarial target class.
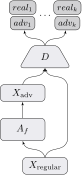
We implement the distributional distance $\mathcal{D}(\cdot,\cdot)$ using an adversary critic $D$ in a GAN‑style framework. The adversary critic $D$ is trained to discriminates real target‑class samples from adversarial ones for each class $y_k$:
$$\min_{D_k} \, \mathbb{E}_{\boldsymbol{x} \sim p_{\text{data}}(\boldsymbol{x} \mid y_k)} \big[ \log D_k(\boldsymbol{x}) \big] \, + \, \mathbb{E}_{y: \, y \ne y_k} \, \mathbb{E}_{\boldsymbol{x} \sim p_{\text{data}}(\boldsymbol{x} \mid y)} \big[ \log\big(1 - D_k\big(\mathcal{A}_f(\boldsymbol{x}; y_k)\big)\big) \big]$$
The classifier $f$ is optimized to be accurate on clean inputs and to confuse the critic on its targeted adversarial examples:
$$\min_{f} \, \mathbb{E}_{\boldsymbol{x}, y \sim p_{\text{data}}} \mathcal{L}\big(f(\boldsymbol{x}), y\big) \, + \, \lambda \sum_{y_k} \mathbb{E}_{y: \, y \ne y_k} \, \mathbb{E}_{\boldsymbol{x} \sim p_{\text{data}}(\boldsymbol{x} \mid y)} \big[ \log D_k\big(\mathcal{A}_f(\boldsymbol{x}; y_k)\big) \big]$$
To stabilize the adversarial mapping $\mathcal{A}_f$ during training, we introduce an adversarial cycle-consistency loss. This ensures that the mapping $\mathcal{A}_f$ to be approximately reversible: an adversarial example perturbed toward a target class $y_t$ should be close to the original input when perturbed again towards the source class $y_s$:
$$\mathcal{L}_{\text{cycle}}(y_s, y_t) \, = \, \mathbb{E}_{\boldsymbol{x} \sim p_{\text{data}}(\boldsymbol{x} \mid y_s)} \Big[ \big\| \mathcal{A}_f\big(\mathcal{A}_f(\boldsymbol{x}, y_t), y_s\big) - \boldsymbol{x} \big\|_2 \Big], \quad \forall \, y_s \ne y_t$$
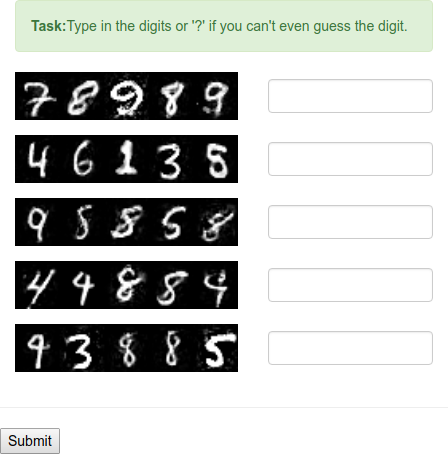
In experiments (e.g., MNIST), our approach outperforms standard adversarial training in robustness. A human study on Amazon Mechanical Turk further confirms that high‑confidence adversarial examples produced by our defense are visually confusing to humans.
Confusing Images
How to Cite
@InCollection{matyasko2018adversarycritic,
  author    = {Matyasko, Alexander and Chau, Lap{-}Pui},
  title     = {Improved Network Robustness with Adversary Critic},
  booktitle = {Advances in Neural Information Processing Systems 31},
  year      = {2018},
  pages     = {10578--10587}
}